A successful AI pilot isn’t necessarily one that produced impressive results. It’s one you understand well enough to repeat.
When an AI pilot goes well, it’s tempting to treat the results as evidence that the organization is ready for a broader rollout. But there’s a question that doesn’t always get enough attention:
“How much of that success came from the technology, and how much came from the circumstances surrounding it?”
Maybe the person running the pilot had spent weeks studying the system, learning its limitations, and figuring out how to work around problems before anyone else encountered them.
Maybe the pilot was conducted in a department with unusually well-maintained source material, or with people who already understood the task well enough to recognize and correct questionable outputs.
Or maybe the workflow was so closely tailored to the needs of one group that it worked beautifully there, but wouldn’t translate nearly as well to another department.
None of these necessarily makes the pilot a failure. But they do matter when deciding whether to expand it.
Before scaling an AI workflow, we should be able to explain what made it successful. That includes more than documenting the prompts or configuration. We need to know what information went in, what human review was required, what errors occurred, how much work went into correcting them, and what conditions might cause the workflow to fail.
We also need to know whether those conditions will hold when the workflow moves out of the pilot environment and into ordinary operations.
What happens when the unusually capable person running the pilot isn’t available? When the source material is less reliable? When the workload increases enough to expose problems that a small sample never revealed?
Those aren’t reasons to abandon a promising pilot. They’re reasons to examine its results more carefully.
A pilot demonstrates that a workflow can succeed under a particular set of conditions. It doesn’t necessarily establish that those conditions exist elsewhere in the organization, or that they can be reproduced.
Sometimes the next step should be another pilot in a different department or under different conditions, rather than a broader rollout.
And that’s why I think evaluating the results deserves at least as much attention as designing and conducting the pilot itself.
Before deciding whether to expand, organizations need to examine not just what worked, but why it worked, what it required, where it struggled, and how well the conditions that produced those results represent the environment in which the workflow will actually operate.
A successful pilot is evidence worth investigating. It isn’t, by itself, a decision to scale.
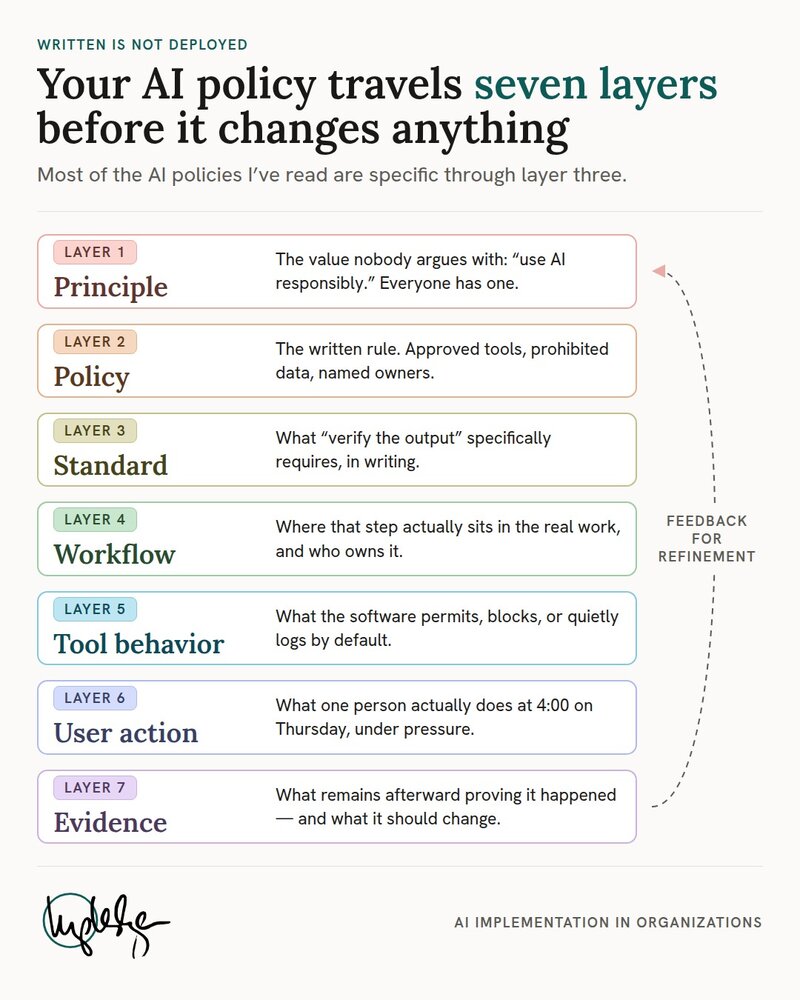
My first comment on the post
Further reading: Dare Bello and John Hastings, “Governing Bring Your Own AI: A Parameterized Maturity Model” (September 2026 preprint).
https://arxiv.org/abs/2609.05236
The authors examine the gaps that arise when employees use personal AI accounts outside enterprise identity and security controls. They propose governance supported by technical controls and human practices; their numerical results come from a parameterized model, with empirical validation still to come.
My connection here is what happens when the work produced in those accounts enters an organization’s shared knowledge. If the finished document travels but its sources and review record don't, someone inherits an answer without the evidence needed to check it.